
Train embedding models with composable PyTorch losses, hard-example miners, distances, reducers, and regularizers. Use them in your own training loop for retrieval, clustering, recognition, or learning from pairs and triplets.
Docs for humans · Documentation source
Install from PyPI with uv or pip:
uv pip install pytorch-metric-learning
pip install pytorch-metric-learning
The core package needs only PyTorch and NumPy. Optional extras add the Faiss
retrieval backend, pytorch-metric-learning[faiss], and scikit-learn for the
NMI/AMI clustering metrics, pytorch-metric-learning[clustering].
Version 3 requires Python 3.12 or newer, PyTorch 2.14.0 or newer, and NumPy 2.5.3 or newer. Upgrading from version 2? Read the release notes and look up old names in the migration guide. The version 2 documentation remains available.
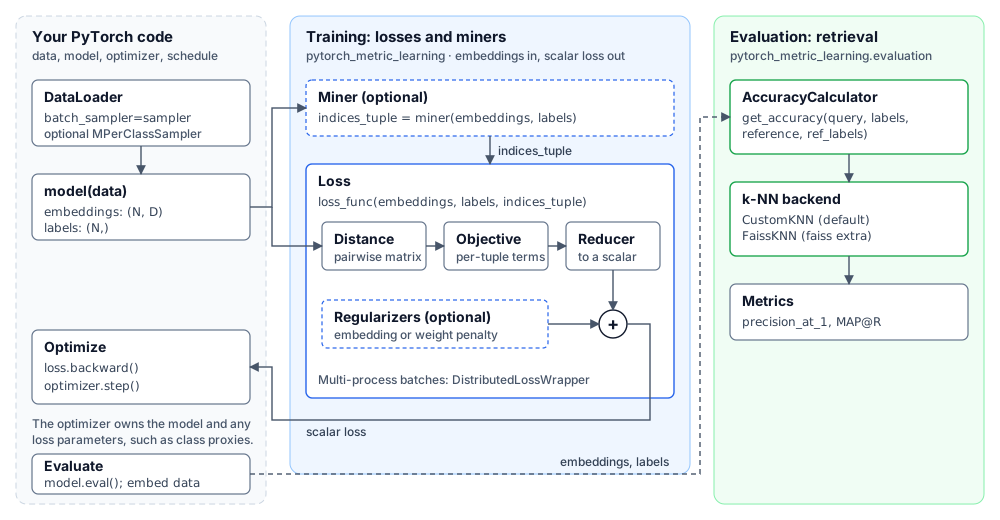
Your model produces one embedding per input. Equal labels identify positive pairs; different labels identify negatives. Here a contrastive loss pulls positive pairs together and pushes negatives apart:
import torch
from pytorch_metric_learning import losses

torch.manual_seed(17)
model = torch.nn.Linear(8, 4)
optimizer = torch.optim.SGD(model.parameters(), lr=0.1)
data = torch.randn(12, 8)
labels = torch.arange(4).repeat_interleave(3)
loss_func = losses.ContrastiveLoss(neg_margin=1.4)

optimizer.zero_grad(set_to_none=True)
loss = loss_func(model(data), labels)
loss.backward()
optimizer.step()
The model returns embeddings shaped (12, 4) and labels have shape (12,).
This loss L2-normalizes embeddings by default. It averages active positive and
negative pair penalties separately, then adds them. See the
contrastive-loss contract for distances,
margins, and reduction options.
The documentation starts with a task index and a concepts overview of embeddings, tuples, distances, loss terms, and reducers. Every component page states its signature, defaults, tensor contract, and paper, and the recipes show complete training and evaluation code.
See CONTRIBUTING.md. Thanks to all contributors, upstream projects, and supporters.
If you use this library in your research, please cite the PyTorch Metric Learning paper:
@article{Musgrave2020PyTorchML,
  title={PyTorch Metric Learning},
  author={Kevin Musgrave and Serge J. Belongie and Ser-Nam Lim},
  journal={ArXiv},
  year={2020},
  volume={abs/2008.09164}
}