Dive brief
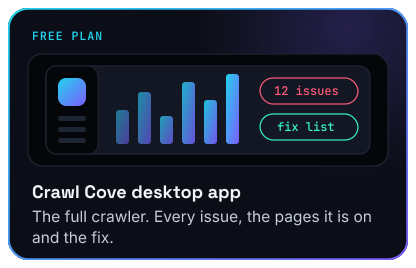
- The crawler: a desktop app that crawls your site and lists every issue, the pages it is on and the fix. The free plan covers 1 project and 1,000 URLs a crawl. No account, no card.
- The kit: 14 open-source tools for the jobs around a crawl. Redirects, sitemaps, robots.txt, hreflang, schema, CI checks.
- The rule: the crawler runs on your machine and your crawl data stays there.
Crawl Cove is a desktop SEO crawler with a free plan.
These are the open-source tools we wrote around it. Take what you need.

Every site looks calm from the surface. Then you send something down with a lamp.
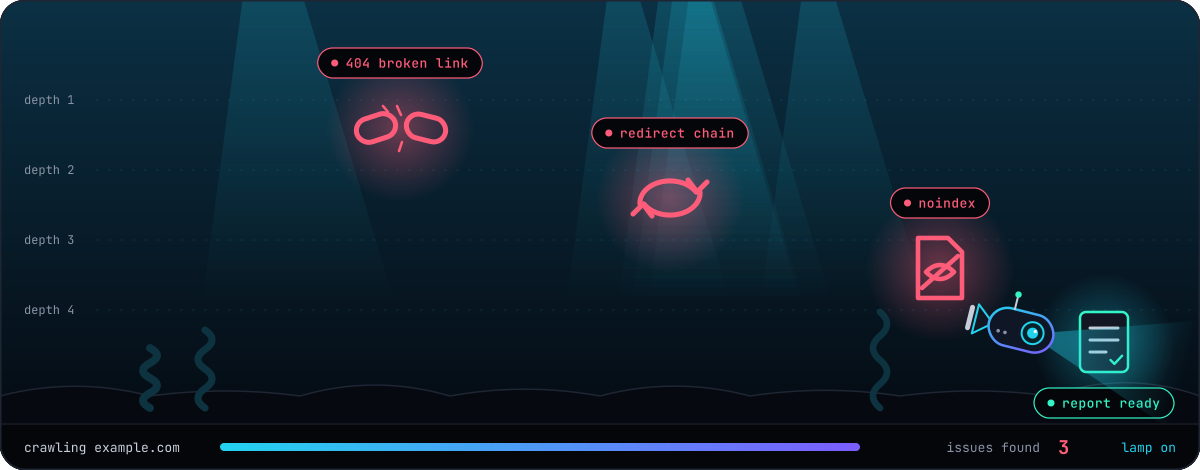
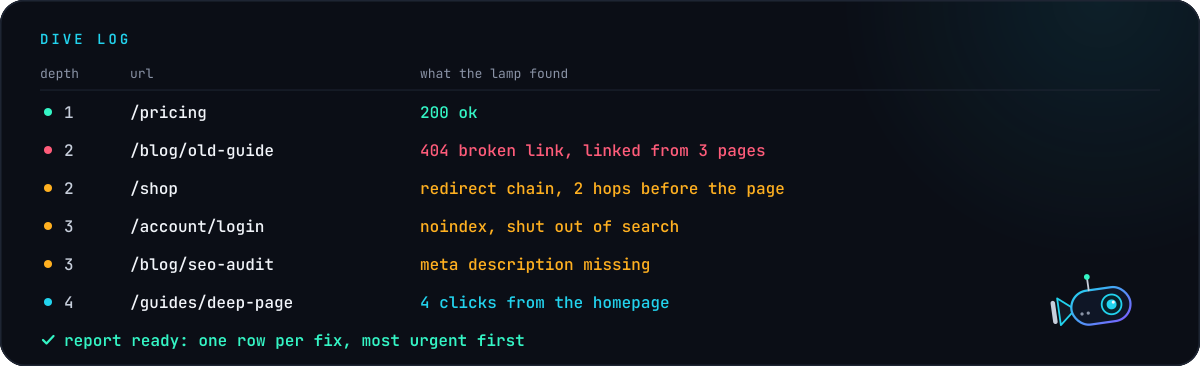
What the lamp picks out. A crawl follows every internal link the way a search engine does, and logs what it meets on the way down:
- Broken links and the pages that link to them
- Redirect chains and loops
- Pages shut out of search by noindex or robots.txt
- Missing or duplicate titles, meta descriptions and H1s
- Canonical, hreflang and structured data mistakes
- Pages that sit too many clicks from the homepage
The desktop app does all of it in one crawl and turns the log into a fix list. The tools below each do one of those jobs from a terminal or a pipeline.

Fourteen small tools and one large one. Each card opens its repo.
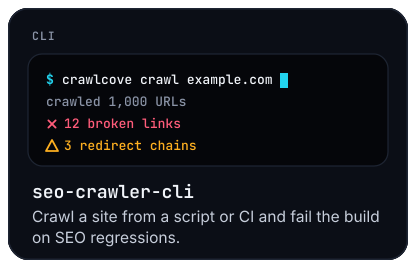
- seo-crawler-cli: Crawl a site from a script or CI. Checks status codes, redirect chains, titles, meta descriptions, H1s, canonicals, noindex and broken links, and fails the build on regressions.
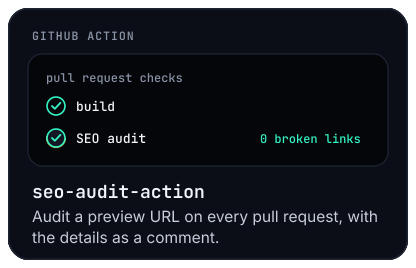
- seo-audit-action: Crawl a staging or preview URL on every pull request. Fails the check on broken links, missing titles, noindex and redirect chains, with the details as a PR comment.
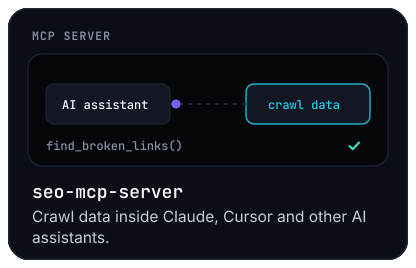
- seo-mcp-server: Crawl a site, list SEO issues, inspect pages and find broken links from inside Claude, Cursor and other AI assistants.
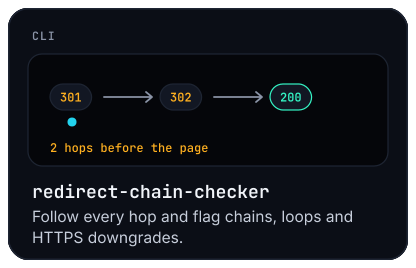
- redirect-chain-checker: Follow every hop of a URL's redirects and flag chains, loops, HTTPS downgrades, meta refreshes and redirects to error pages.
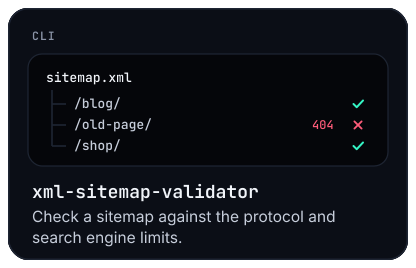
- xml-sitemap-validator: Check a sitemap or sitemap index against the sitemaps.org protocol and search engine limits. Flags bad URLs, lastmod dates and cross-host entries.
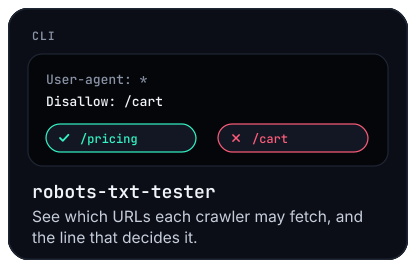
- robots-txt-tester: Fetch and lint a robots.txt, test which URLs each crawler may fetch and see the deciding line. Fails deploys that block the site.
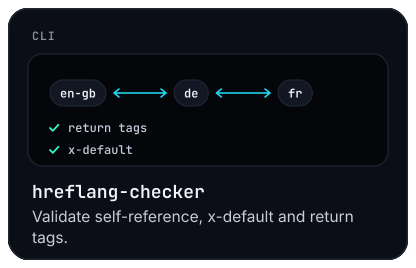
- hreflang-checker: Validate the hreflang tags on a page or across a whole XML sitemap, including self-reference, x-default and return tags.
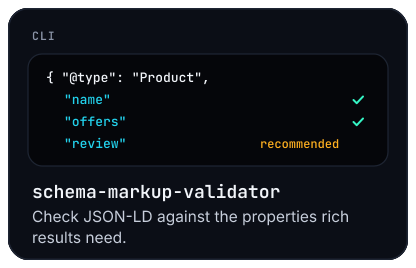
- schema-markup-validator: Check every schema.org node on a page against the required and recommended properties for rich results.
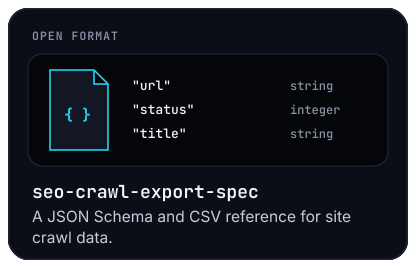
- seo-crawl-export-spec: An open format for site crawl data: JSON Schema and CSV column reference, with a real sample export and a validator script.
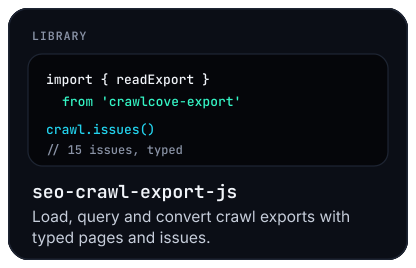
- seo-crawl-export-js: Load, query and convert site crawl data in JavaScript and TypeScript, with typed pages, issues by type and status filters.
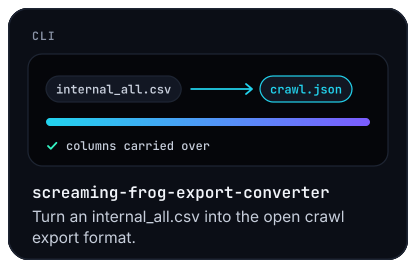
- screaming-frog-export-converter: Turn an SEO Spider internal_all.csv into the open JSON crawl export format, with a report of which columns carried over.
- seo-audit-google-sheets: An Apps Script add-on that turns a site crawl export into an audit workbook: pages, issues by type, pages by status and title and meta flags.
- wordpress-seo-connector: Bulk-apply fixes from the Crawl Cove desktop crawler to Yoast SEO, Rank Math, SEOPress or AIOSEO, with a change log and one-click revert.
- seo-chrome-extension: On-page SEO checker with an AI visibility report: which AI crawlers can read the page, snippet blocks, llms.txt and extractability. Nothing leaves the browser.
Most of them run with one line and nothing to install first:
npx github:CrawlCove/redirect-chain-checker https://example.com/old-page
Divers have a rule about glowing things on the seabed. Ignore it this once.
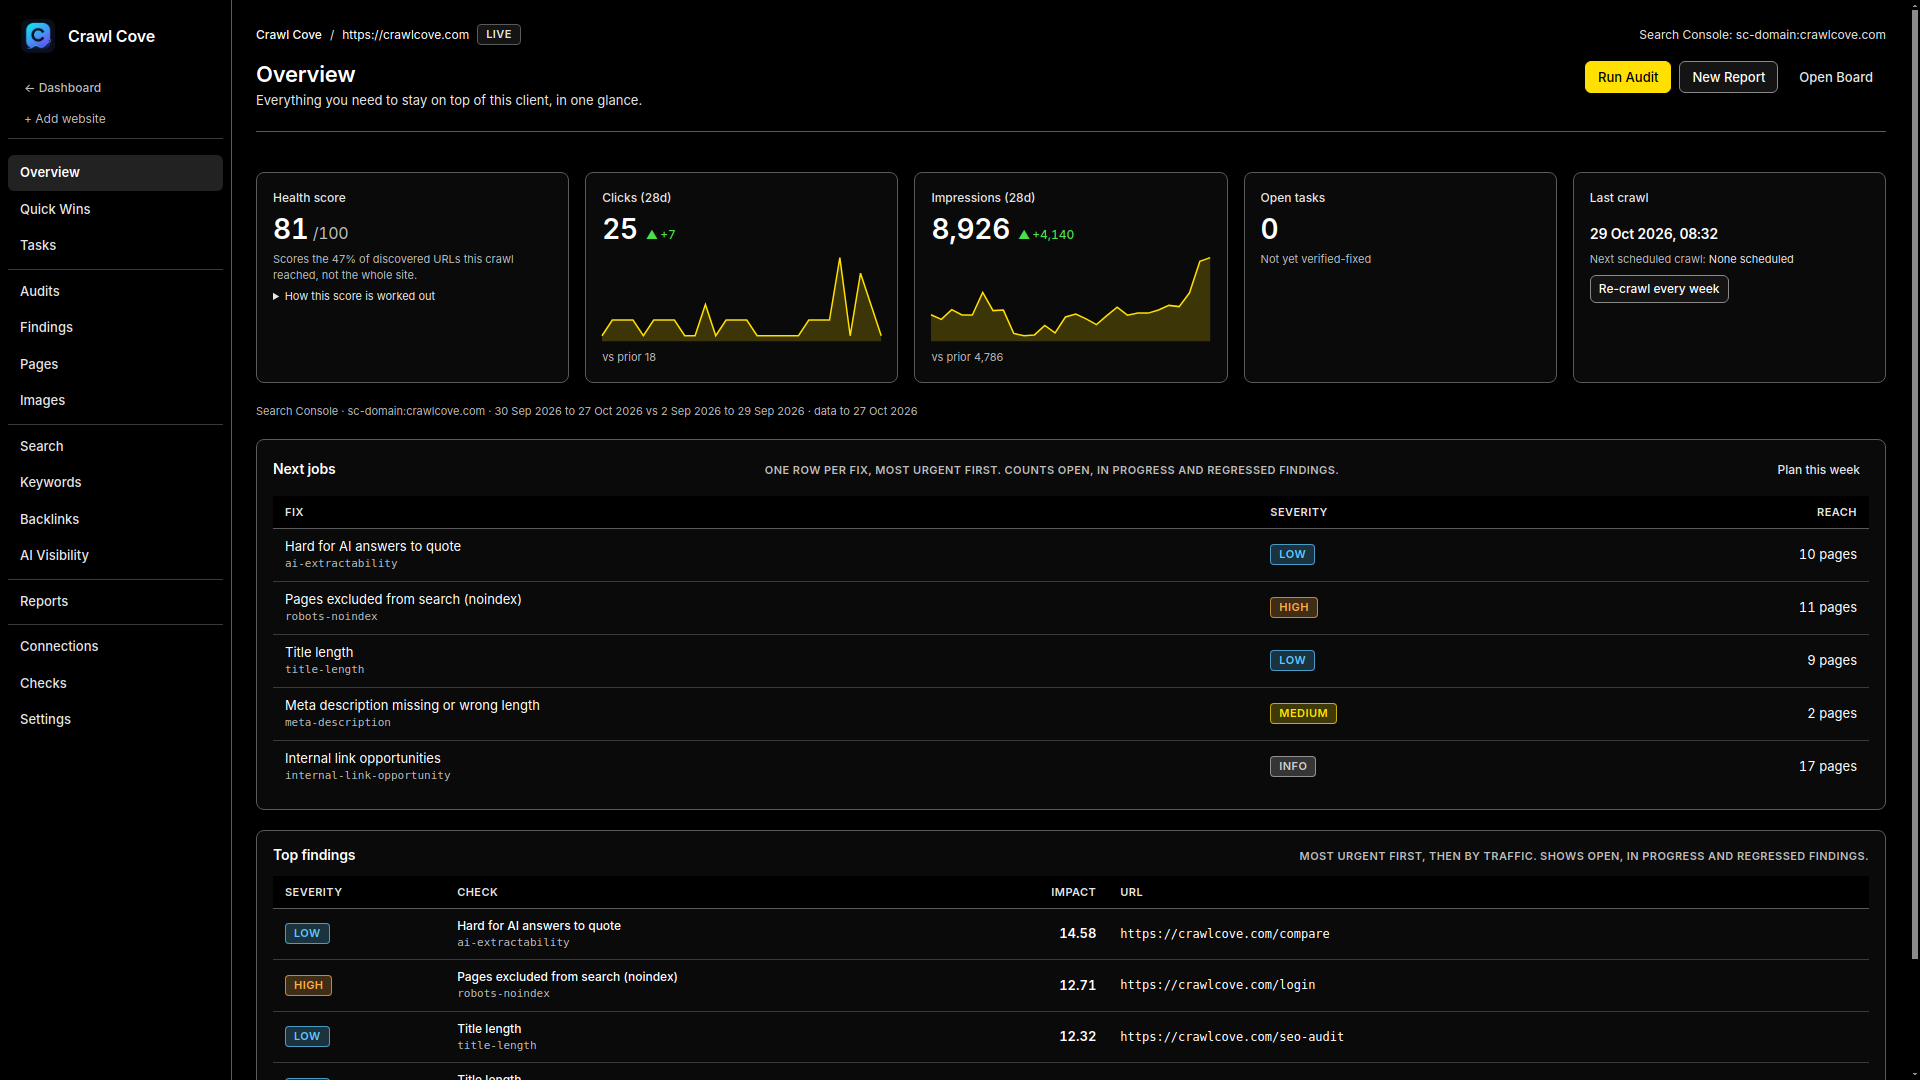
The Crawl Cove desktop app. It crawls a site, scores it, and gives you one row per fix with the pages it touches, most urgent first. The free plan is not a trial and does not expire:
- 1 project
- 1,000 URLs a crawl
- Every check and its fix
- The Google Search Console connection
Paid plans add more projects, uncapped crawls, exports, PDF reports and scheduled crawls. See the plans.

The lantern fish takes questions. It is brief, because it is a fish.
What is Crawl Cove?
A desktop SEO crawler. It crawls your website the way a search engine does, finds broken links, redirect chains, noindex pages, missing titles and more, and tells you which pages to fix and how. Website: crawlcove.com.
Is the desktop app free?
There is a free plan with no account, no card and no expiry: 1 project and 1,000 URLs a crawl, with every check, its fix and the Search Console connection. Paid plans add more projects, uncapped crawls, exports, PDF reports and scheduled crawls. Download it here.
Are the tools on this page open source?
Yes. They are MIT licensed, apart from the WordPress connector, which is GPL v2 like WordPress itself.
Do I need the desktop app to use them?
No. The checkers and the CLI run on their own with
npx and Node. The WordPress connector is the exception: it applies fixes found by the desktop app.
Can I run SEO checks in CI?
Yes. seo-audit-action crawls a preview URL on every pull request and fails the check on broken links, missing titles, noindex and redirect chains. The CLIs exit non-zero on failure, so they fit any pipeline.
Where does my crawl data go?
Nowhere. The desktop crawler and the command-line tools run on your own machine, and the Chrome extension keeps everything in the browser.