





I am a Third-Year IT Undergraduate (2024 – Expected 2028) at Ho Chi Minh City University of Natural Resources and Environment (HCMUNRE), focused on Data Analytics (DA) and Data Engineering (DE). I use SQL, Python, Power BI, and modern cloud data tools (AWS, Snowflake, Airflow 3, dbt Core) to turn raw data into reliable datasets, actionable insights, and testable business recommendations.
| Domain | Technologies & Libraries |
|---|---|
| Data Analytics & BI | SQL (Joins, CTEs, Window Functions) • Python (Pandas, NumPy, SciPy, mlxtend) • Power BI (DAX, Power Query) • Microsoft Excel |
| Visualization & Methods | Plotly (Sankey, Funnel) • Seaborn • Matplotlib • squarify • RFM • Cohort Retention • Apriori • Pareto ABC • IQR Auditing |
| Cloud & Warehousing | AWS (CloudFormation IaC, S3 Versioning, SQS + DLQ, CloudWatch, SNS, Redshift Serverless, IAM) • Snowflake Data Cloud |
| Orchestration, Modeling & CI | Apache Airflow 3 (AssetWatcher, Astro CLI, Cosmos) • dbt Core • Kimball Star Schema • Docker • GitHub Actions CI (Ruff, cfn-lint, Pytest) |
- 🏅 dbt Fundamentals — Verified Credential — Issued by dbt Labs (Credential ID:
daf3523f-38ca-48fe-9b95-548d6ca7da8d)
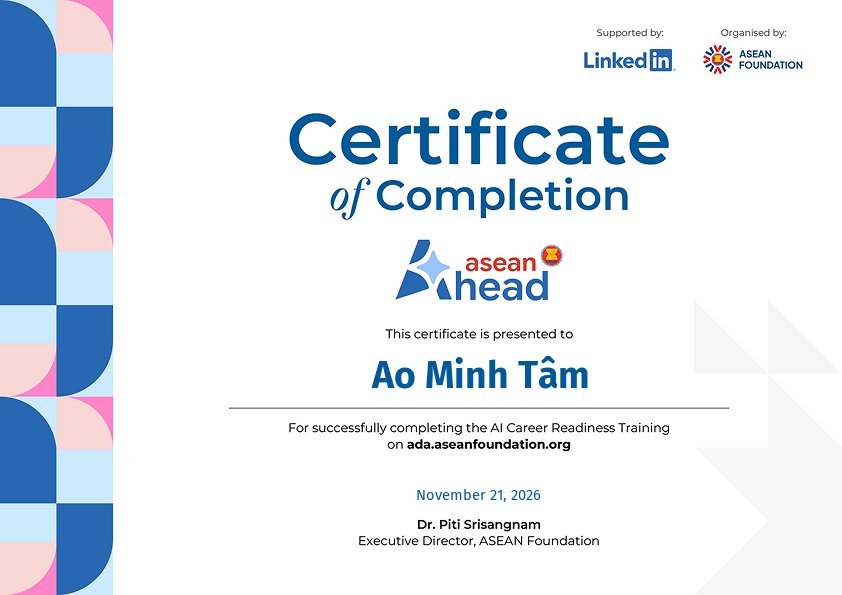
Verified course completion credential demonstrating core competency in modular SQL models, incremental materializations, automated schema/data quality testing, and DAG lineage documentation using dbt Core and dbt Cloud. - 🎓 AI Career Readiness Training — Certificate of Completion — Organised by ASEAN Foundation, supported by LinkedIn (
ASEAN Ahead, Nov 2026)
Certificate of Completion for structured training in practical AI fluency, prompt workflows, and digital career readiness.
- aws-data-pipeline (V5.0.1 — CloudFormation IaC, Event-Driven ELT & CloudOps)
- Stack: AWS (CloudFormation, S3, SQS + DLQ, CloudWatch, SNS, Redshift Serverless, IAM), Airflow 3 (
AssetWatcher, Cosmos), dbt Core, Docker, Pytest - Provisioned declarative AWS CloudFormation IaC (15 core + 4 conditional resources) ingesting 99,441 Olist orders (
~120 MB). Replaced cron polling with Airflow 3AssetWatcher(20sSQS Long Polling, 0 empty runs), Two-Phase DB-atomicTEMP TABLEswaps with CSV header & empty-stage guards,ops.pipeline_ingestion_audit+ At-Least-Once Safe ACK (900s), SQS DLQ (maxReceiveCount=3), 4 CloudWatch Alarms + SNS email (5.0.0 live-verified on AWS17/17tasks +11dbt schema tests + DLQ Redrive; 5.0.1 passing21/21Python unit tests +3DAG tests + offlinedbt parsein CI).
- Stack: AWS (CloudFormation, S3, SQS + DLQ, CloudWatch, SNS, Redshift Serverless, IAM), Airflow 3 (
- dbt-snowflake-data-pipeline
- Stack: Snowflake, dbt Core, Apache Airflow (Astronomer Cosmos), Docker, Python, SQL
- Automated cloud ELT platform orchestrating Snowflake transformations via containerized Airflow & Astronomer Cosmos inside an isolated
dbt_venvon TPC-H benchmark data, materializing Medallion Staging & pre-joined Kimball Star Schema marts with automated schema/referential checks.
- customer-rfm-segmentation-analysis
- Stack: Python, Pandas, NumPy, Seaborn, squarify
- Quantile RFM segmentation (
pd.qcut, snapshot2024-01-01, distinctOrderID.nunique(), grossSales) across 51,290 line-items (25,728unique orders,17,415customers, 2020–2023 simulated dataset). Showed top 2 tiers (<29% of users) generate >53% of revenue (Champions: 13.56% users / 32.8% revenue), isolated 833 Cant-Lose accounts (4.78% users, 10.0% value), and formulated A/B-testable campaign hypotheses.
- abc-inventory-analysis
- Stack: Python, Pandas, NumPy, Seaborn, Matplotlib, IQR Anomaly Auditing
- Pareto ABC profitability segmentation across 51,290 transactions (
25,728orders,17,415accounts, 2020–2023, using the dataset's pre-computedProfitcolumn), finding 12.94% of Group A VIPs (2,254 users) generate 80% of cumulative profit. Audited a 500-gift budget shortfall (1,754 gap) to propose a measurable tiered physical-plus-digital retention pilot.
- cohort-retention-analysis
- Stack: Python, Pandas, NumPy, Seaborn, Matplotlib
- Time-based cohort retention heatmaps across B2B/B2C segments (51,290 transactions, 2020–2023) exposing a 1%–3% Month-1 drop-off cliff. Eliminated left-truncation bias by anchoring
FirstPurchaseDateglobally acrossdf_salesand observed B2B cyclical restock bumps (5%–6% at Months 5 and 8).
- product-conversion-funnel-analysis
- Stack: Python, Plotly (Funnel), Pandas, NumPy, Seaborn
- Sequential unique-session conversion funnels (
/products→ PDP →/cart→ Order Confirmation/thank-you-for-your-order) across 261,231 catalog sessions (472,871 sitewide sessions, 32,313 orders; Maven Fuzzy Factory, 2012–2015). Calculated Net Revenue After Refunds, uncovered the "Love Bear Paradox" (10.0% catalog share vs. 55.6% cart-add rate) and ~66% cart-to-order drop-off, proposing A/B recovery flows.
- user-journey-sankey-analysis
- Stack: Python, Plotly (Sankey), Pandas, NumPy
- Interactive Plotly Sankey DAGs across 1.18M+ pageview records (
261,231engaged multi-page sessions out of472,871total sessions,32,313orders). Eliminated circular DAG crashes via.rank()prefixes, reduced join RAM bloat withusecolsand pre-aggregation, and pinpointed mobile drop-off and cross-sell paths (Mr. Fuzzy -> Love Bear).
- market-basket-analysis
- Stack: Python, mlxtend (Apriori), TransactionEncoder, Pandas, NumPy, Seaborn
- Apriori association rules mining (0.5% min support) with basket deduplication across
25,728baskets preventing OOM crashes. Surfaced high-affinity cross-sell pairs (Lift up to 4.25, 45% confidence) to design A/B bundle hypotheses.
- pareto-revenue-analysis
- Stack: Python, Pandas, NumPy, Matplotlib, Seaborn
- Quantified SKU-level Net Revenue After Refunds across 32,313 orders (Maven Fuzzy Factory, 2012–2015) using Pareto 80/20
cumsumcurves. Validated that 3 core SKUs drive ~82% of net revenue (with 1 flagship SKU holding 45.2% concentration risk).
📍 Ho Chi Minh City, Vietnam • Open to Data Analyst & Data Engineer Intern Opportunities